What I built
The approach
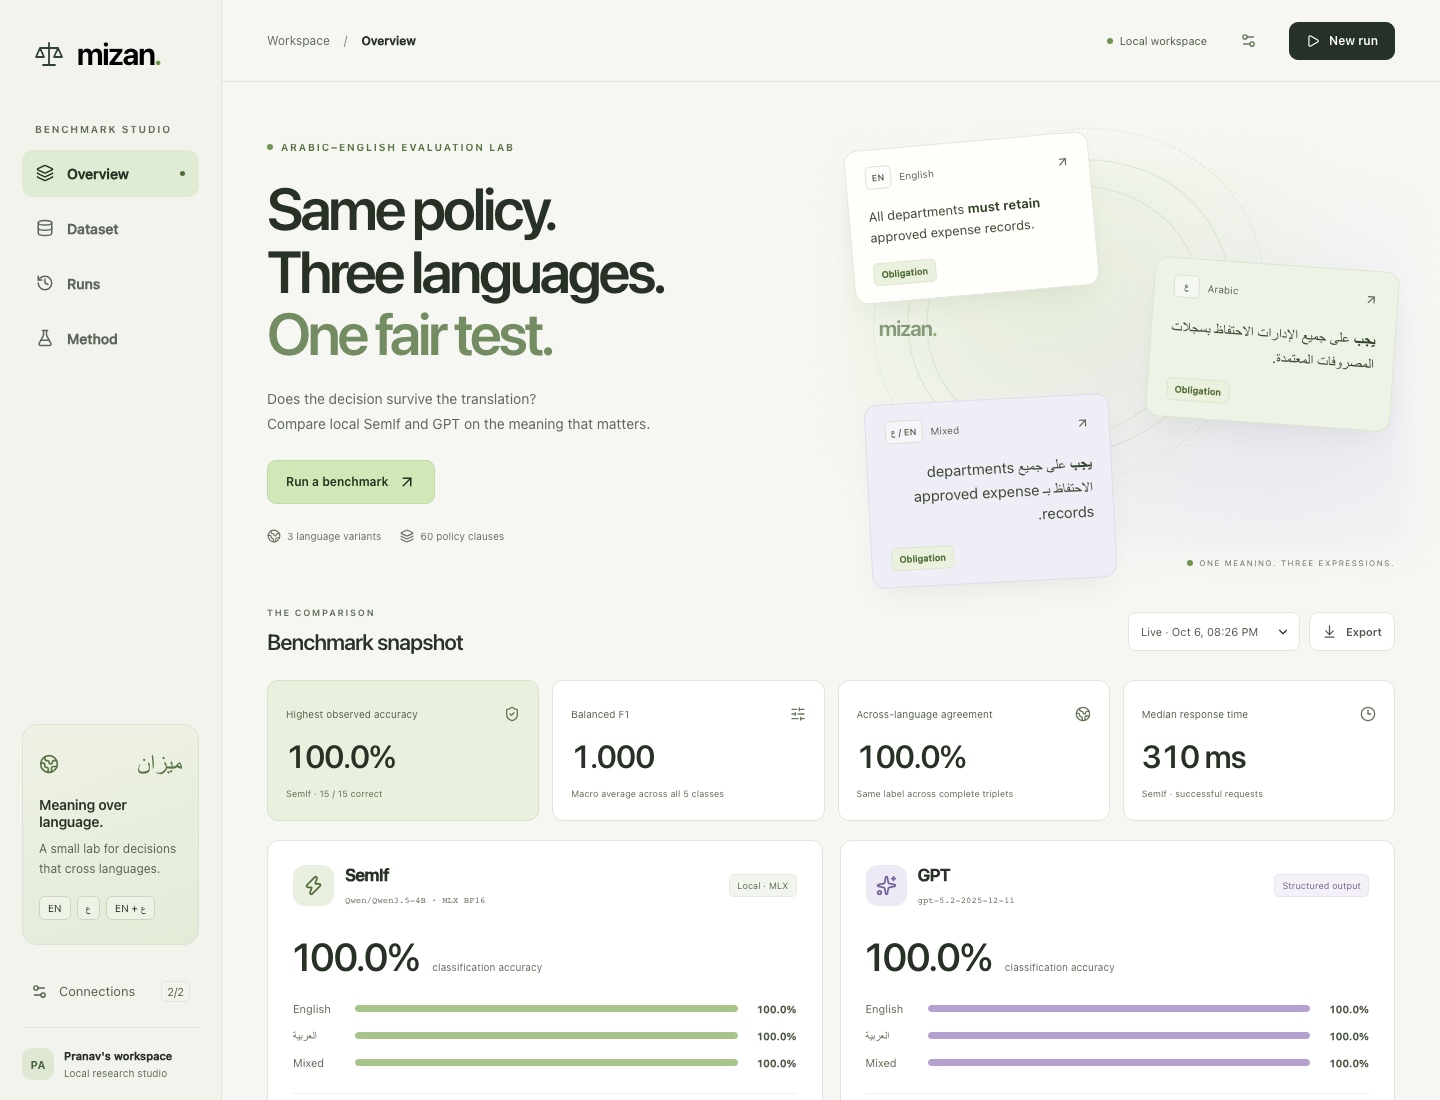
A benchmark that classifies policy clauses as obligations, prohibitions, permissions, definitions or procedures, in English, Modern Standard Arabic and mixed-language versions of the same clause. It compares a local 4B model scored by direct option logits with a hosted GPT baseline.
Full live run (6 Oct 2026)
One run on 60 synthetic clauses (20 English, Arabic and mixed triplets) that have not yet had bilingual expert review. Both models scoring 100% means this set is too easy to separate them. Latency compares a warm local Mac with a hosted API, not equal hardware.
Follow the workflow
Each policy clause exists in English, Modern Standard Arabic and a mixed version with the same meaning.
Engineering decisions
Test meaning, not translation
Each clause comes as an English, Arabic and mixed triplet, so the benchmark can check that all three receive the same label.
Score the local model without generation
The local model picks a label from option logits with zero generated tokens, so there is no free text to parse.
Cap spend before a run starts
A conservative cost estimate is checked against a per-run ceiling before any hosted call is made.
Limitations & next steps
Have a bilingual domain expert review the clauses, add a harder held-out set with negation and exceptions, and repeat runs across prompts before comparing models.